-
When should a B2B sales team use lead enrichment?
-
The Okki-Go data enrichment setup checklist: 6 quality steps
-
1. Clean the source list before you connect anything
-
2. Define what 'enriched' means before you configure the tool
-
3. Enrich fields that change an action, not every field the platform offers
-
4. Run a 50–100 record pilot and spot-check it like a human
-
5. Set up field mapping and test with five records, not five thousand
-
6. Respect the API rate limit and monitor job completion, not just job start
-
1. Clean the source list before you connect anything
-
Common enrichment mistakes I still see
What is lead enrichment? In plain terms, it is the process of taking an incomplete lead record and filling in the blanks: a work email, a direct dial, company size, industry, tech stack, or a recent intent signal. Done well, data enrichment turns a CRM full of names into a list your SDRs can actually act on.
I run data quality for a B2B SaaS team, and I review every enrichment batch before it reaches sales — roughly 1,500 records a month, and more during campaign pushes. The question I hear most often is a good one: what is lead enrichment and when should a B2B sales team use it?
Here is the short version. Enrichment solves missing data. It does not solve a broken ICP filter, a messy source list, or a sequence that does not have any personalization logic behind it. When your target list is sound and the gaps are blocking outreach, enrichment earns its keep. When you hope it will rescue a bad list, you will end up with more details about bad accounts and a bigger invoice.
The checklist below is the one I run before spending a single credit. I will use Okki-Go as the reference because it is the sales intelligence platform I have used in my last two deployments. Every step applies to other tools too. The button names change; the quality problems do not.
When should a B2B sales team use lead enrichment?
Use this as a quick sorting gate before you evaluate any platform.
Lead enrichment makes sense when:
- You have a high-volume list — think 1,000 or more records — and a meaningful share of those records are missing work emails, role, or firmographic fields.
- Your routing rules or sequence branches depend on fields that are empty. If company size changes the pitch, enrichment is not a nice-to-have.
- You need verified contact data at scale and do not want SDRs spending minutes per lead on manual research.
I would hold off when:
- Your target list is under roughly 250 records. Manual research can give better context at that size, and enrichment is harder to justify.
- Your ICP is not agreed yet. Enriching an unvalidated segment just makes a bad list more expensive.
- No one can explain what changes because of the enriched data. That is the clearest signal that the problem is not missing data.
To be fair, manual research is not a bad option for small, high-touch campaigns. At scale, enrichment wins on consistency and repeatability. It is not human versus tool; it is about whether the workflow can scale without errors.
The better question is not 'what fields can we add?' It is 'which missing field changes the email we send or the routing step we take this week?' If no field changes an action, do not enrich yet.
The Okki-Go data enrichment setup checklist: 6 quality steps
Once you decide enrichment is the right answer, the setup should include the same checks every time. Here is the sequence I use.
1. Clean the source list before you connect anything
This is where I made my own rookie mistake. In my first big enrichment push, I was so focused on the new tool that I skipped basic list hygiene. We spent roughly $2,400 in credits enriching duplicate and suppressed records before anyone noticed. The tool was not the problem; the unpdated source list was.
- Remove duplicates by email, domain, or LinkedIn URL.
- Exclude suppression lists and do-not-contact records.
- Exclude contacts that are already in an active sequence or already have a verified email from a prior campaign.
- Add a stable primary key to every row so you can match results back cleanly.
Checkpoint: after cleaning, your list should have one row per unique contact. If the row count barely changes, the upstream list generation needs work before enrichment will help.
2. Define what 'enriched' means before you configure the tool
Before you switch anything on, write down what 'enriched' means for your team. Not just field names. For every field, define the values you will actually accept.
- Email: 'verified' can mean syntax-only, catch-all, role-based, or a real mailbox response. Decide which statuses are allowed for outreach. A role-based address like info@ can be technically valid and still useless when your goal is a conversation with a person.
- Company fields: decide which source is the source of truth. If your CRM says 120 employees and the enrichment source says 150, what happens on conflicts?
- Intent data: define the time window. An intent signal from nine months ago may no longer mean anything.
I learned that one the hard way. In a 2025 pilot review, 14% of the records that the vendor dashboard labeled 'verified' were role-based or catch-all addresses. The data was not wrong; the spec was missing. We had not said what we were actually willing to send to.
Checkpoint: your team should be able to agree on a one-line definition of a usable record. For example: a personal work email verified within the last 60 days, plus a confirmed company size and industry.
3. Enrich fields that change an action, not every field the platform offers
Sales intelligence platforms can return dozens of fields per record. That does not mean you should map all of them. Every field you add carries a cost: integration effort, data review, and the risk that your team starts trusting a field nobody actually validated.
If your current sequence only branches on industry and company size, enrich industry and company size. If your SDRs write manual notes and need recent trigger events, only then add intent data. A field with no consumer is not an asset; it is noise.
Okki-Go data enrichment is waterfall-based, which means it can check multiple sources until a field is confirmed. I like waterfall for coverage. But you should choose your fields before the waterfall runs; otherwise you will end up with forty populated fields and only four that mean anything to the people using them.
Checkpoint: for every field in your setup, write down the sequence step or routing rule that will use it. If you cannot write one, remove the field.
4. Run a 50–100 record pilot and spot-check it like a human
This is the step that feels slow, which is exactly why most people skip it. Do not skip it.
Pull a random sample, not the first fifty rows from your CSV. Enrich those records, then open them one by one. Does the email address look like it belongs to a person? Does the company size match what you already know? Is the industry field accurate or just a broad guess?
In a 2025 pilot, we rejected a batch where the vendor counted records as enriched even though the sample showed stale addresses and outdated company data. The dashboard numbers looked fine; the actual records would have burned three outbound sequences. The human check caught it before we spent the full budget.
It does not scale, and that is fine. The pilot is not about scale. It is about calibrating your quality threshold before the full run.
Checkpoint: define an acceptance threshold before the pilot. We reject a pilot if fewer than 85% of records meet our usable-record definition. Your number may differ, but say it out loud before the run.
5. Set up field mapping and test with five records, not five thousand
The Okki-Go setup flow after a good pilot is fairly straightforward: connect the source, define the unique key, map the fields, and choose overwrite behavior. The part that causes the most damage is overwrite behavior.
Set the system to not overwrite validated fields. If an SDR already confirmed a direct email through a phone call, enrichment should not replace it with another guess two days later. Keep the value that has human proof behind it.
Then send five real records through the entire flow. Follow them all the way into your CRM or sequence tool. Confirm that the mapped fields land where you expect and that no existing data got degraded.
Checkpoint: the five test records should look exactly like a finished lead from your best SDR: correct fields, no null overwrites, no duplicate contacts created.
6. Respect the API rate limit and monitor job completion, not just job start
Every sales intelligence platform API has rate limits — usually a requests-per-minute limit plus a monthly credit allowance. The exact numbers for your plan are in the API dashboard or provider documentation, not in the sales deck. Verify them before you schedule a large run.
Large batches fail quietly. If you push 50,000 records through a single job and the API rate limit kicks in, some records will finish, some will queue, and some may come back as 'no result.' There is a big difference between 'not found' and 'failed because the request never completed.' Your logs need to distinguish between the two.
This becomes even more important if you use agent-native prospecting, where an AI SDR can call enrichment in real time rather than processing a nightly batch. Real-time enrichment is more sensitive to rate limits because there is no queue. If the enrichment call fails, decide what happens: does the message go out without the data, or does the sending step wait? The right answer depends on your sequence, but you need to know which failure mode you have chosen.
Checkpoint: ask the person running the integration how you will know a job failed. If the answer is 'the system sends an email,' test that email. Do not assume it works.
Common enrichment mistakes I still see
After years of reviewing enrichment output, these are the patterns that keep coming back:
- Enriching without cleaning. There is no point appending new data to duplicates, suppressed contacts, or records already in an active sequence.
- Buying every field. Large field coverage sounds impressive until you realize your sales team only uses four of them. The rest just create noise.
- Skipping the manual pilot. Dashboards are built to show success. A random sample opened by a human will show you the truth.
- Treating enriched data as permanent. People change jobs, companies change sizes, and intent signals decay. Add a freshness check before campaigns, not after a bounce report.
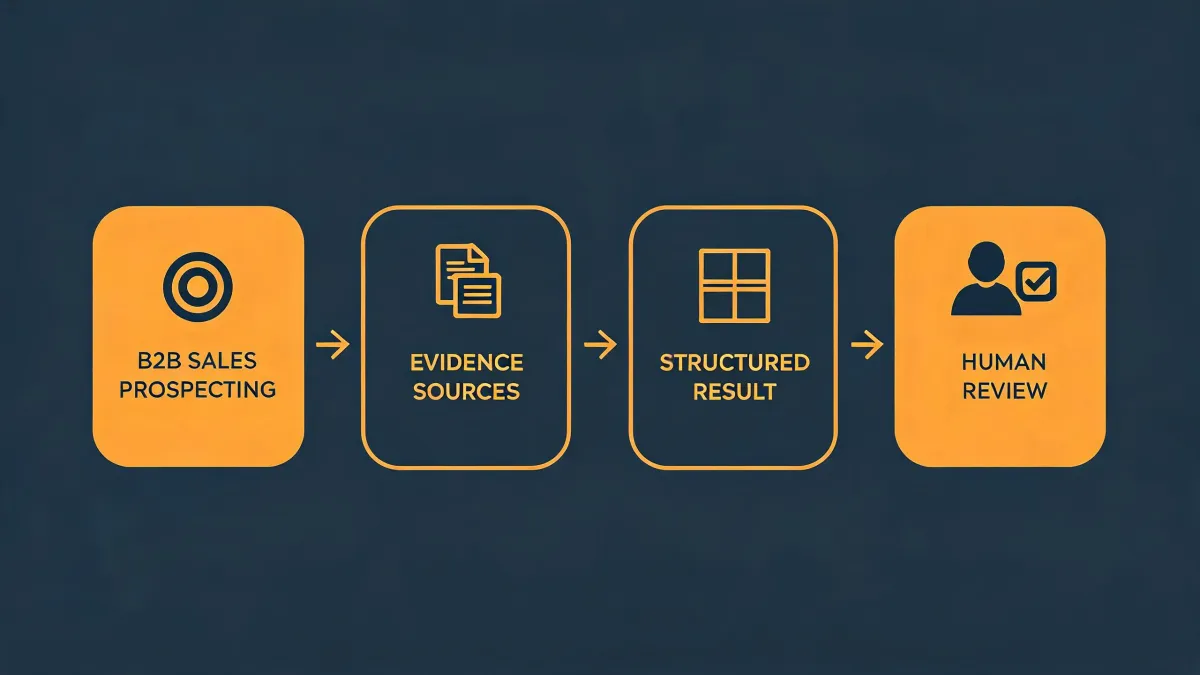
Bottom line: lead enrichment is worth paying for when it removes a gap that changes the next sales action. It is not worth paying for when the list, the ICP, or the personalization logic is still broken. When you do run enrichment, use the full chain: clean the source, define the spec, pick actionable fields, pilot like a human, test the mapping in small batches, and respect the API rate limits. The cost of skipping a checkpoint is not just a bad dataset. It is a sales team that stops trusting the CRM — and once that trust is gone, no amount of new data brings it back.