-
What Should Revenue Operations Teams Evaluate in Reply Classification?
-
Dimension 1: Rules and Keywords vs. Native AI Logic
-
Dimension 2: Point Tools vs. a Multi-Agent Platform
-
Dimension 3: Pricing Transparency (The One That Made Me Build a Spreadsheet)
-
Dimension 4: What Happens After the Label?
-
So Which One Should You Choose?
I'm a procurement manager at a 40-person B2B SaaS company. I've managed our sales tool budget—about $120,000 a year—for six years, negotiated with 20+ vendors, and logged every invoice in a cost tracking system I built after getting burned on hidden fees twice. So when someone asks me what should revenue operations teams evaluate in reply classification, I don't start with model accuracy. I start with the total cost of acting on the reply.
Every AI outbound tool these days claims to do AI reply classification. But there are two very different ways to deliver it. One is a rules-and-automation stack (think n8n, Zapier, Make, or a basic tagging tool). The other is native AI built into a platform, like the Relevance AI multi-agent platform. Those are not the same purchase. Here's the comparison I'd run.
What Should Revenue Operations Teams Evaluate in Reply Classification?
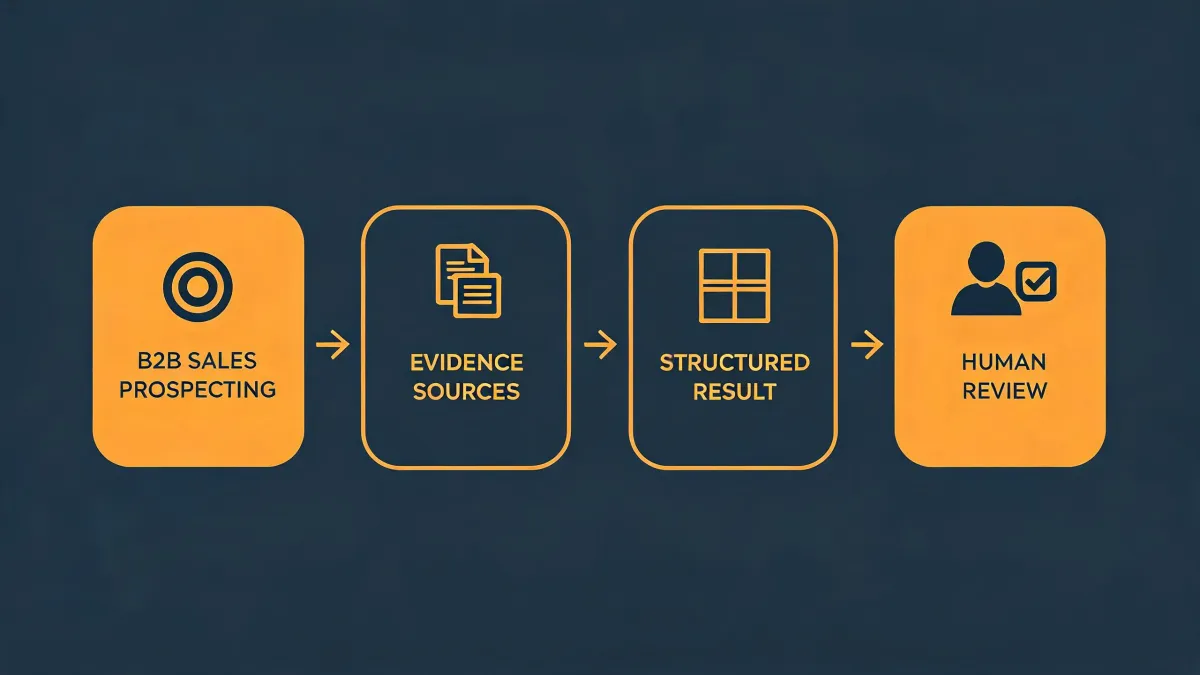
In an AI outbound sequence, the AI sends emails, and then replies come back. Reply classification is the step that decides what happens next: “positive” moves toward a meeting, “not interested” stops the sequence, “out of office” pauses, “question” routes to a human or an agent. If that step is wrong, your email sequences make bad decisions.
I look at four things: classification logic, workflow integration, pricing transparency, and what happens after the label. Accuracy matters, but accuracy is only a means. The end is control.
Dimension 1: Rules and Keywords vs. Native AI Logic
Rules and keywords. You build a workflow: if reply contains “unsubscribe,” mark it unsubscribe; if it contains “meeting” or “pricing,” mark it hot. It's transparent and cheap. You can trace every decision. That's also its weakness. “Send pricing” is not always a hot lead. “Can you send pricing” can mean “I want to know if this is too expensive.” “Not right now but keep me posted” doesn't fit into positive or negative.
When I audited our 2023 sequence data, I found that 14% of replies needed judgment a simple rule would have missed. I'm not gonna pretend I have a favorite model. I have a favorite spreadsheet. The spreadsheet said rules work until volume grows, and then the exceptions multiply.
Native AI. A model reads the full reply, remembers the conversation, and labels intent with context. It can handle “keep me posted” as its own state. It can even suggest a draft response. But it's not magic. You need to test it on your own replies, because “positive” for one team means “meeting booked” and for another means “they answered one acronym question.”
Here's the surprising part: for a small outbound volume, rules can be fine. Actually, that's not entirely true. Rules can be fine if your offer is simple and your replies are obvious. The gap only appears at scale, because that's when nuance becomes common. The bigger cost isn't the mislabeled replies. It's the hours your RevOps person spends adding keywords, debugging edge cases, and rebuilding workflows after every campaign change. When I audited our 2023 spending, that maintenance line was the one that surprised me. The tool was cheap. The labor wasn't.
I also assumed “same specifications” meant identical results across vendors. Didn't verify. Turned out one provider's “positive” included “maybe,” and another's didn't. If I'd run a shared sample of 100 replies before signing anything, I'd have caught the mismatch in an afternoon.
There's a compliance angle too. Per FTC Business Guidance on Advertising (ftc.gov/business-guidance/advertising-marketing), marketing claims must be truthful, not misleading, and substantiated. If your AI SDR replies to a “positive” lead with “I reviewed your website” but never did, the classification didn't fail—the claim did. A classifier can't fix a false statement.
Dimension 2: Point Tools vs. a Multi-Agent Platform
The second dimension is workflow. A stand-alone classification API is like a really good switchboard operator. It routes calls, but it doesn't know what your company sells, what's in your CRM, or whether a prospect already met you at a trade show. A multi-agent platform is different. One example is the Relevance AI multi-agent platform: it gives you AI SDR agents that handle outbound, manage email sequences, enrich leads, pull intent data, and act on a classified reply immediately.
That's where the workflow comparison gets concrete. A point tool sends a tag to your CRM. Then you need a second tool to add a task. Then a third to update the sequence. Each step is an integration, and each integration is a potential failure point. When I compared TCO during a 2024 vendor switch, the “simple” stack had nine moving parts. The platform had one. That's not automatically better—it can be overkill—but it's a real difference.
One feature worth evaluating specifically: Relevance AI Notion integration. I used to roll my eyes at “Notion integration” (oops, I was wrong). It matters because the agent can pull the current sales playbook from Notion before it classifies and responds. That means reply classification isn't just a label; it's a workflow that respects your latest pricing page and objection handling notes. But it also means your Notion content has to be current. Garbage playbook, garbage replies. That's a hidden cost, but a manageable one.
Dimension 3: Pricing Transparency (The One That Made Me Build a Spreadsheet)
If you've compared AI tools, you know the game. The quote looks fair. The implementation fee appears after. The “per 1,000 classifications” line is in the data sheet, not the sales call. The sequence upgrade? Separate. The Notion integration? Actually, that's an extra. (Ugh.)
I still kick myself for not documenting one vendor's verbal promise during a renewal. If I'd gotten it in writing, we'd have had grounds to dispute a $450 hidden fee. Now I ask one question before “what's the price”: “What's not included?” The vendor who lists all fees upfront—even if the total looks higher—usually costs less in the end.
Here's the TCO comparison I'd run:
- Rules stack: low monthly cost, high setup and maintenance labor, every campaign edit costs hours.
- Point AI tool: moderate monthly cost, usage charges for classification, integration maintenance.
- Multi-agent platform: higher monthly cost, but it includes email sequences, reply classification, playbook integration, and room for agents to act.
None of these is universally wrong. But the “cheap” point tool can end up costing more than the platform when you add per-query pricing and the human who has to babysit it.
Dimension 4: What Happens After the Label?
Classification is only useful if something good happens next. For revenue operations, that means asking: Can I set the threshold for human review? Can I see why the agent marked a reply “positive”? Can I override the result and have the sequence respect that? Does the next email sequence action make sense?
In an AI outbound context, a “meeting requested” reply should trigger a scheduling link. A “question about pricing” should trigger a constrained response from your approved playbook. A “not interested” should stop future emails and add the contact to a suppression list. The point is not to let this run without oversight. I'd never recommend a setup where an AI agent follows up with zero human review. That's how you get an angry LinkedIn post.
This is why I like evaluating platforms that include the response step, not just the label. Relevance AI is one of those: the agents can classify, draft, and route—while you keep an approval step where it counts. But don't buy it just because it sounds autonomous. Buy it if it lets you audit the logic and intervene.
So Which One Should You Choose?
Choose a rules-based stack if your outbound volume is under a few thousand emails a month, someone on your team enjoys maintaining workflows, and replies are mostly simple strings like “unsubscribe” or “not interested.”
Choose a point AI tool if you already have a solid automation spine and only need better labeling.
Choose a multi-agent platform like Relevance AI if you're running AI outbound at scale, your email sequences change often, and you want the classification to feed directly into an agent's next action.
Don't ask which has the highest accuracy. Ask which one your revenue operations team can afford to run well. That's the answer I'd defend in a room full of procurement people—and I've got a spreadsheet to back it up.